The VRAM Wall: Why Local AI Demands High-End Hardware
AI-generated image · Bay Street Wire
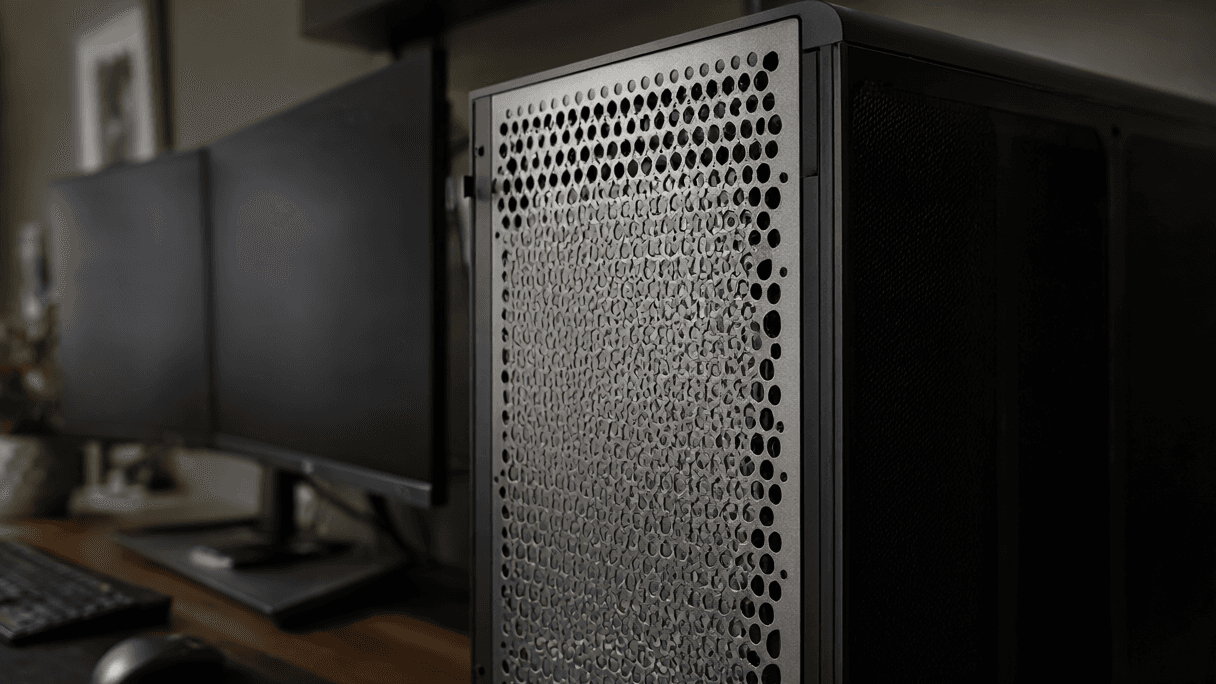
While software agents like Hermes make local LLMs accessible, the sheer memory requirements of large-parameter models create a steep hardware barrier for consumers.
The push toward local AI is driven by a desire for privacy and a move away from the cloud services managed by companies such as Google, Microsoft, OpenAI, and Anthropic. However, as The Verge first reported, the ability to run powerful large language models (LLMs) locally is heavily dependent on a machine's memory capacity.
In testing conducted by The Verge's Antonio G. Di Benedetto, the disparity between standard consumer hardware and the requirements for high-performance local AI is stark. Di Benedetto utilized an M5 Ultra Mac Studio equipped with 256GB of unified memory to run the Qwen 3.8 Flash Next model. This specific model contains 125 billion parameters and requires approximately 105GB of space to operate.
While Di Benedetto noted that a $12,000 computer is not necessary for simple tasks—such as creating a basic daily briefing via a cron job—the most capable models require significant RAM investments.
Industry efforts to address this gap are appearing in both the Mac and PC ecosystems. Apple continues to market its Mac desktops for local AI, while a new line of RTX Spark Windows machines is arriving with up to 128GB of RAM. Other hardware being tested for smaller Qwen models includes the M6 Mac Mini, M5 MacBook Air, and the Asus TUF Gaming A14 featuring an AMD Strix Halo processor.
On the software side, tools like the open-source Hermes Agent provide a self-hosted application for macOS, Windows, and Linux to integrate local LLMs. While the software simplifies onboarding, the underlying hardware remains the limiting factor for those wishing to run complex, high-parameter local AI.